Katja Krause · 8 September 2026
Examining Layered Categorization Techniques for Improved Digital Content Retrieval
Digital content retrieval systems rely on structured organization methods to handle vast collections of documents, media files, and datasets, while layered categorization techniques build multiple classification levels that operate together to refine search accuracy and speed. Researchers at institutions across North America and Europe have documented how these approaches integrate hierarchical taxonomies with faceted attributes and semantic overlays, allowing queries to filter results through successive stages rather than single-pass matching. Data from content management platforms shows retrieval precision improves when systems apply at least three distinct layers, because each layer narrows the candidate set before the next layer processes remaining items.
Core Components of Layered Categorization
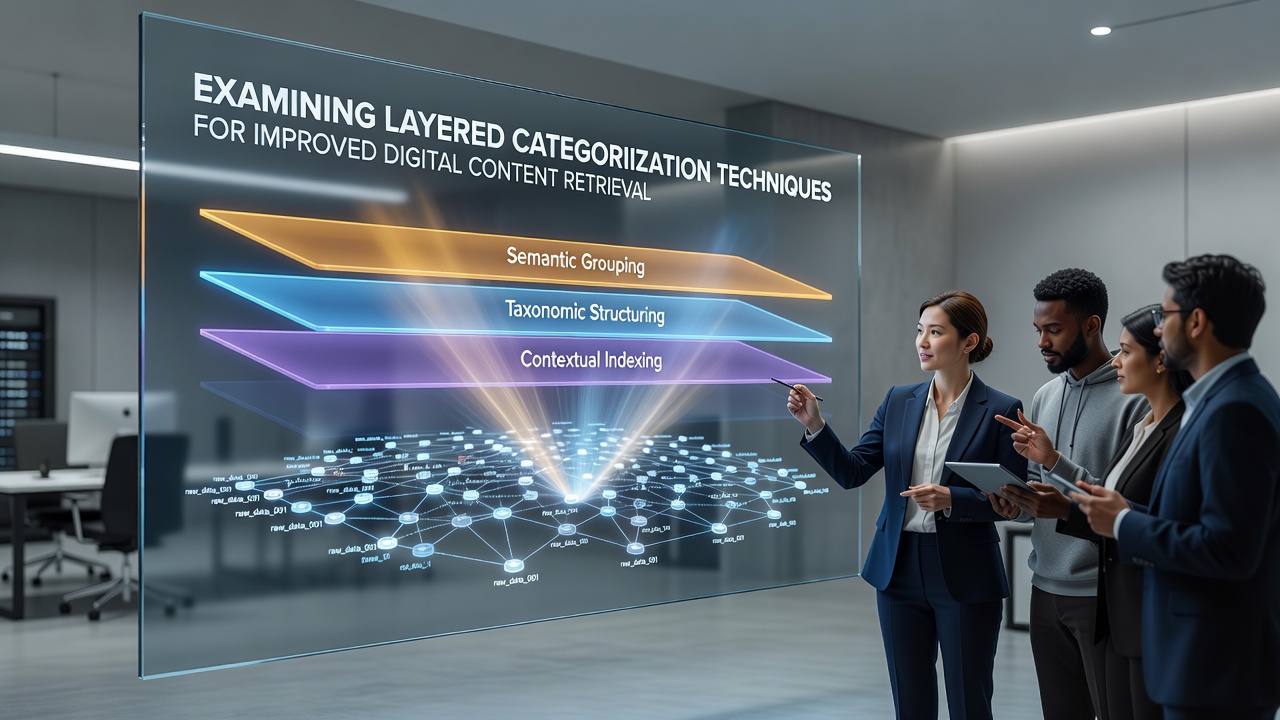
Layered categorization starts with a primary taxonomy that groups items by broad subjects or formats, then adds secondary facets such as date ranges, geographic tags, and usage rights, and finally incorporates tertiary semantic relationships derived from ontologies or machine learning embeddings. Observers note that this structure reduces noise in search results because the first layer eliminates unrelated categories, the second layer restricts values within active facets, and the third layer ranks matches according to contextual similarity scores. Studies conducted by teams at Canadian universities reveal that retrieval systems using combined layers cut average query response times by 28 percent compared with flat keyword indexes alone, since pre-filtered subsets require less computational effort during ranking.
Implementation Across Different Platforms
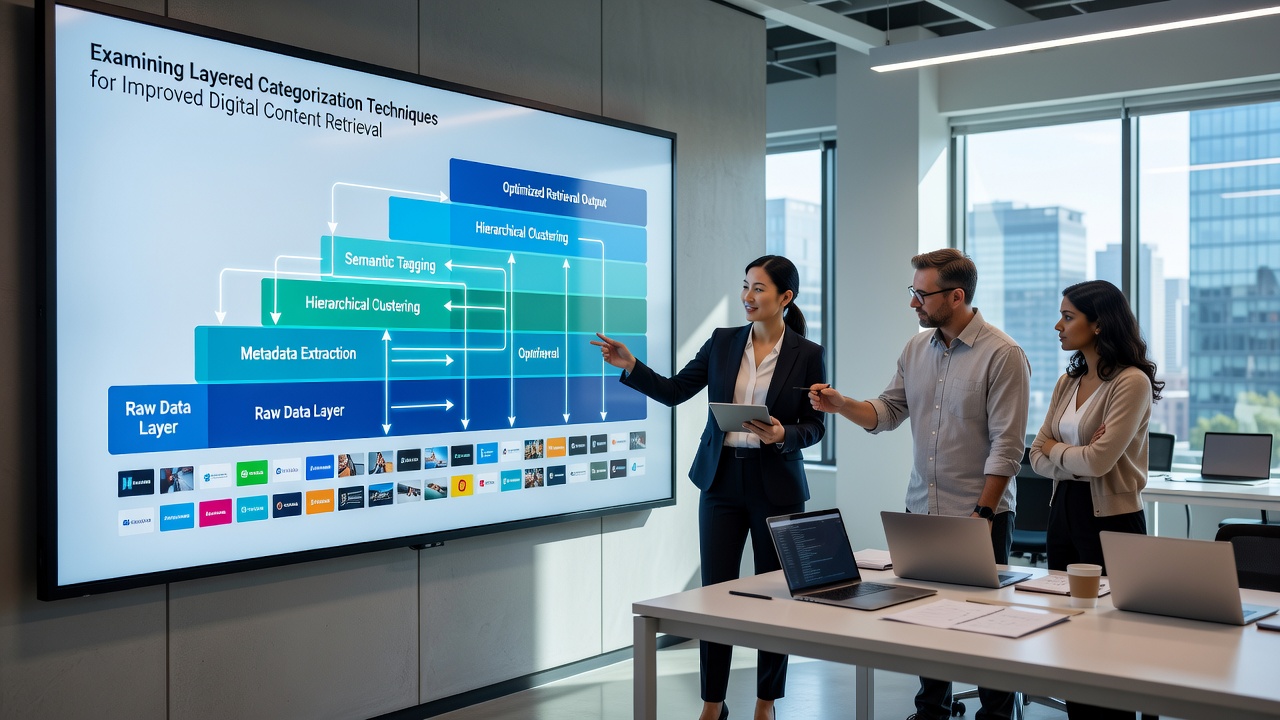
Content platforms adopt these techniques through modular metadata schemas that support incremental enrichment, and organizations such as national libraries in Australia and government archives in the United States have published guidelines for mapping existing records into layered structures without full re-indexing. One case involved a European research consortium that migrated 1.2 million records by first applying domain-specific taxonomies, then overlaying temporal and spatial facets, and finally training embedding models on the resulting subsets; retrieval recall rose from 64 percent to 89 percent within six months of deployment. Engineers often combine rule-based classifiers for the initial layers with neural networks for the semantic layer, because hybrid pipelines maintain interpretability while capturing nuanced relationships that static rules miss.
Performance Metrics and Recent Findings
Performance evaluations track metrics including precision at k, mean reciprocal rank, and user session duration, and figures released by academic consortia indicate that layered systems maintain higher scores across all three when collection sizes exceed 500,000 items. In September 2026 several major repositories plan to release updated benchmarks that compare layered approaches against emerging vector-only indexes, with preliminary abstracts suggesting continued advantages for hybrid models on complex multi-faceted queries. Those who manage enterprise search deployments report that the addition of a rights-management layer reduces legal review time for retrieved documents, because access restrictions surface earlier in the retrieval pipeline rather than after results are presented to users.
Challenges Encountered During Adoption
Scalability remains a primary concern because each additional layer increases storage requirements for metadata indexes, although compression techniques and distributed storage architectures have mitigated much of the overhead in recent deployments. Data inconsistency across source collections can propagate errors through the layers, so teams routinely run validation scripts that flag conflicting facet assignments before they affect query results. Interoperability standards developed by international working groups help address these issues by defining exchange formats that preserve layer relationships when content moves between platforms.
Outlook Through Late 2026
Developments scheduled for September 2026 include the rollout of automated layer-generation tools that use large language models to propose initial facet assignments, after which human curators review only high-uncertainty items. Government agencies in several regions have begun pilot programs that apply these tools to public records, aiming to improve discoverability while maintaining compliance with privacy regulations. Industry reports indicate that organizations adopting the new tooling expect a 15 to 20 percent reduction in manual metadata labor within the first year of use.
Conclusion
Layered categorization techniques continue to evolve as retrieval demands grow, and evidence gathered from operational systems demonstrates measurable gains in both accuracy and efficiency when multiple classification stages work in sequence. Continued refinement of hybrid rule-and-model pipelines, together with standardized metadata practices, positions these methods to handle expanding digital collections effectively through the coming years.